Assessing the Limitations of In-App Interventions in Addressing LLM-Generated Health Misinformation
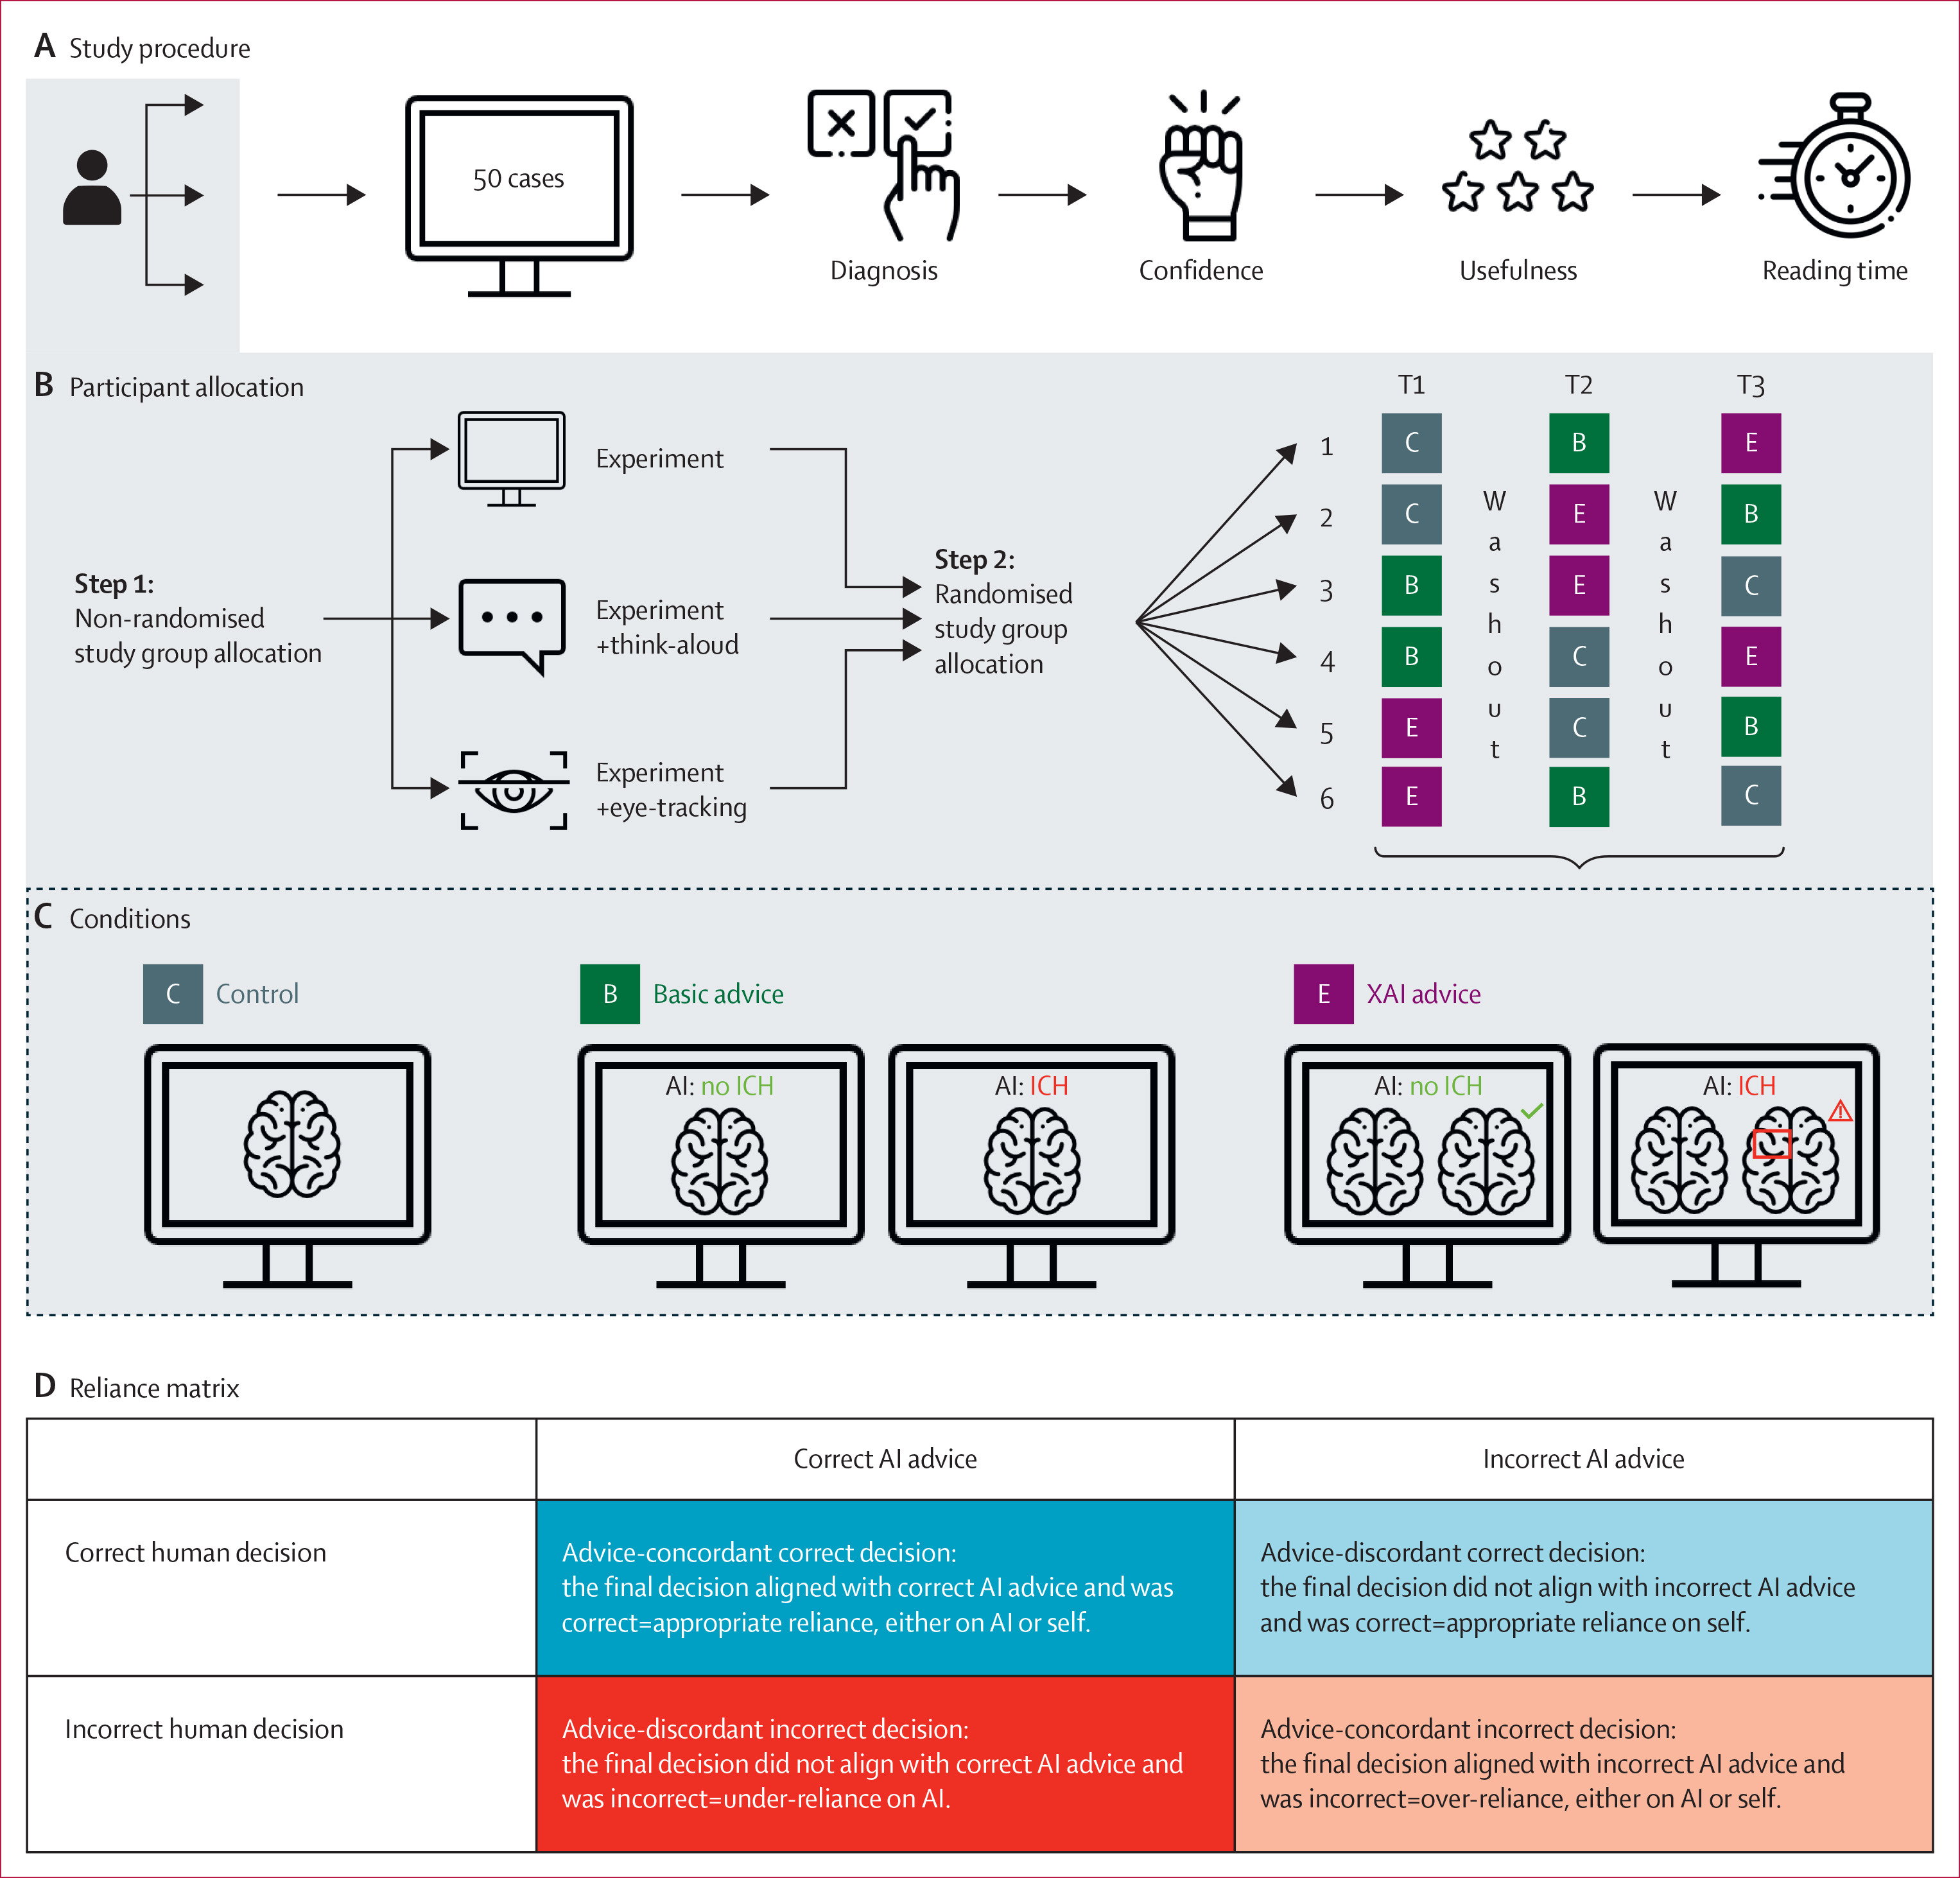
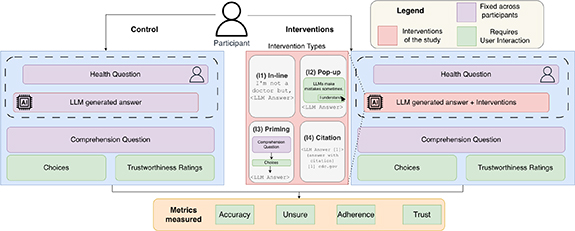
LLM chat apps often warn that “LLMs can make mistakes.” In a user study (N = 217) on LLM-generated answers about reproductive health, infant care, cancer screening, and vaccination, we test in-line disclaimers, pop-ups, priming, and citations, and find that none significantly improve users’ ability to identify health misinformation.
@article{riquelme2026assessing,
  title   = {Assessing the Limitations of In-App Interventions in Addressing {LLM}-Generated Health Misinformation},
  author  = {Riquelme, Vicente and Balloli, Vaibhav and Adam, Hammaad and Li, Xinyi and Miles, Carly and Solomon, Leah Mitchell and Southworth, Elizabeth and Peahl, Alex and Ghassemi, Marzyeh and Bondi-Kelly, Elizabeth},
  journal = {Machine Learning: Health},
  volume  = {2},
  number  = {2},
  pages   = {025024},
  year    = {2026},
  doi     = {10.1088/3049-477X/aea422}
}